How to Create a Proper Sitemap.xml and Robots.txt for Your Website
Vietnamese
Quick answer: Creating a proper sitemap.xml and robots.txt is crucial for SEO. For sitemaps, use a generator or plugin to include all canonical URLs, especially those updated within the last 6 months. Ensure it's under 50MB and lists no more than 50,000 URLs per file. Robots.txt, placed in your root directory, should disallow pages you don't want indexed, like admin areas, but ensure it doesn't block critical CSS/JS files.
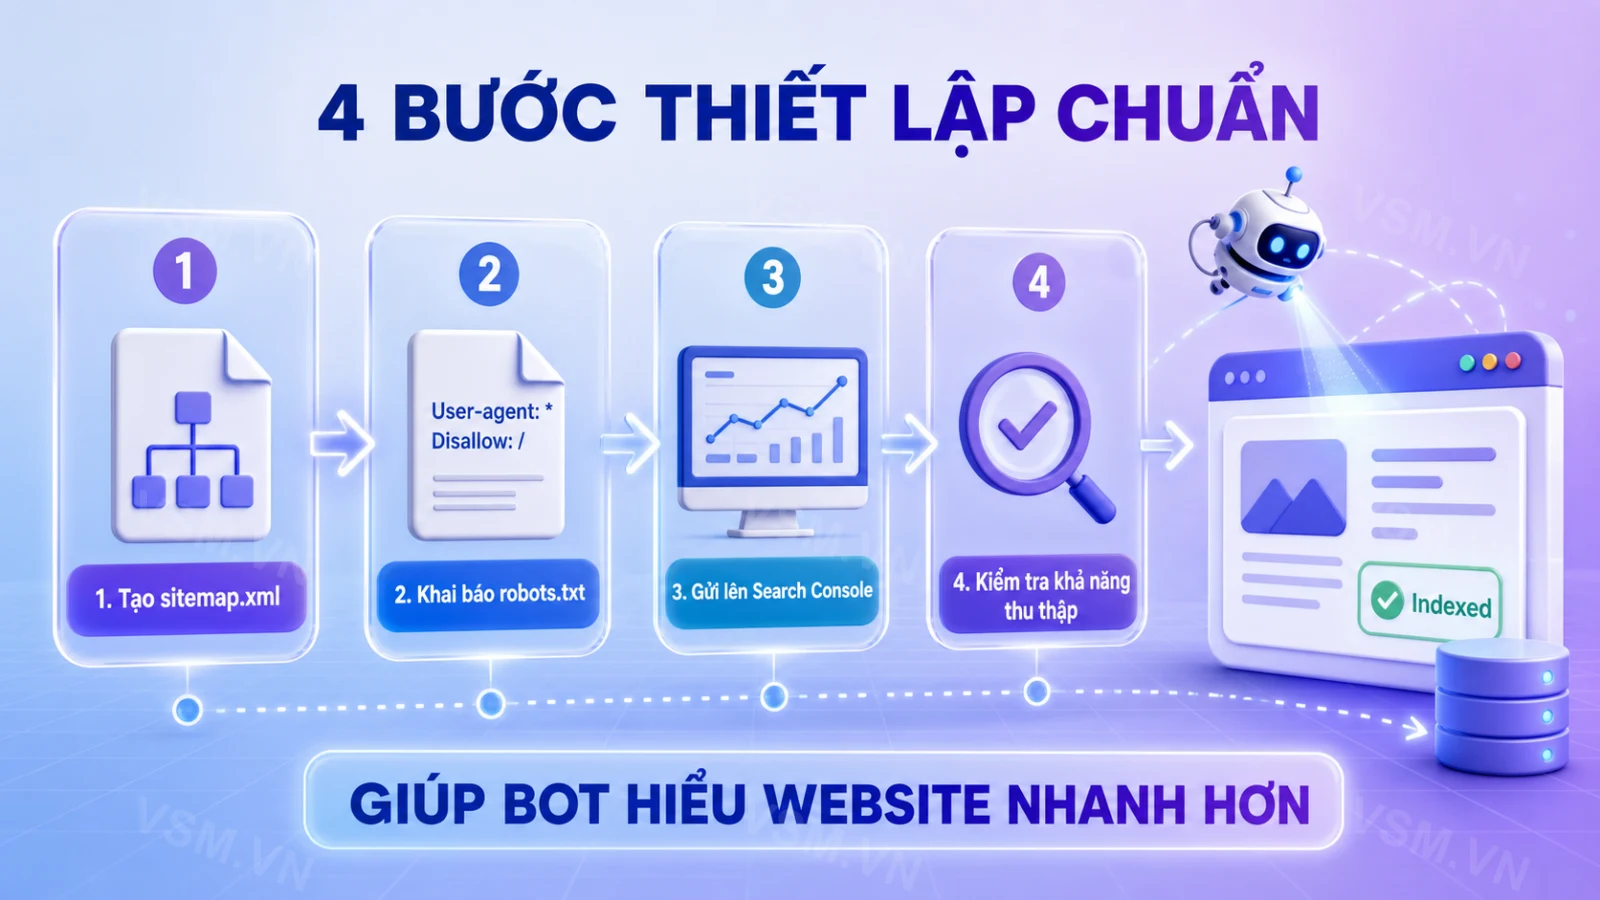
For any website aiming to be discovered and fully indexed by Google, creating a proper sitemap.xml and robots.txt is a foundational technical step that cannot be overlooked. Though these files are small, they determine how search engines "see" and collect data on your site, directly affecting indexing speed and overall SEO effectiveness.
Many website owners, especially those new to SEO, often overlook these files or configure them incorrectly, causing Googlebot to miss important pages or even inadvertently block the entire website from search results. This article guides you on creating, configuring, and checking sitemap.xml and robots.txt for optimal SEO, applicable to both WordPress and custom-coded websites.
What is Sitemap.xml and Why Does Your Website Need It?
Sitemap.xml is an XML file listing the important URLs on your website that you want search engines to crawl and index. Think of a sitemap as a roadmap, helping Googlebot know exactly which pages exist, when they were last updated, and their priority, without having to manually navigate each link.
For websites with complex internal linking structures, many deep pages, or new sites with few external links, sitemap.xml is almost essential to ensure these pages are crawled and indexed on time. Specific benefits include:
- Helping Google quickly discover newly published pages, which is useful for frequently updated news sites and blogs.
- Informing search engines about recently modified pages to prompt timely crawling.
- Improving indexing for pages with few internal links pointing to them.
- Providing index status data in Google Search Console, allowing early detection of errors or pages removed from the index.
Beyond Basic Discovery: Advanced Sitemap Benefits
While the primary role of a sitemap is discovery, its utility extends further, providing subtle yet significant advantages in competitive SEO landscapes:
- Handling Orphan Pages: These are pages on your site that have no internal links pointing to them. Without a sitemap, search engines might never discover them, regardless of their content quality. A sitemap acts as a direct line to these otherwise isolated pages.
- Large Websites and Crawl Budget: For sites with hundreds of thousands or even millions of pages (e.g., e-commerce stores, large forums), crawl budget becomes a critical factor. A well-structured sitemap efficiently directs crawlers to the most important pages, ensuring valuable content isn't missed due to budget constraints.
- Multilingual and Multi-regional Sites: Sitemaps can include annotations for hreflang tags, signaling to search engines the language and regional targeting of specific pages. This is crucial for international SEO, preventing duplicate content issues and ensuring the correct regional version is served to users.
- Image and Video Sitemaps: Beyond standard HTML pages, sitemaps can be specialized to list images and videos, providing search engines with more context about your media content. This can improve visibility in image and video search results. For example, an image sitemap might include details like the image's subject, location, and license, which standard page crawling might overlook.
What is Robots.txt and Its Role in Controlling Crawl?
If sitemap.xml is a roadmap, then robots.txt acts as a traffic sign, dictating which areas bots are allowed to access and which should be avoided. This plain text file is located in the root directory of a website (e.g., vsm.vn/robots.txt) and contains directives guiding crawlers on which paths should or should not be crawled.
Robots.txt is often used to prevent bots from wasting "crawl budget" on unnecessary pages like admin areas, internal search pages, shopping carts, temporary files, or duplicate content pages. Proper control here helps Google focus on crawling the pages that truly add SEO value.
The Nuances of Crawl Control and Robots.txt
While often seen as a simple block/allow mechanism, effective robots.txt management requires a deeper understanding of its implications:
- Crawl Budget Optimization: Googlebot has a finite amount of time and resources it can allocate to crawling your website. By disallowing access to low-value pages (e.g., login pages, thank-you pages, internal search results, filter combinations that generate thin content), you ensure that your crawl budget is spent on pages with high SEO potential. This is particularly important for large websites.
- Preventing Indexation of Unwanted Content (with caveats): While robots.txt prevents crawling, it does not guarantee non-indexation. If other websites link to a page that is disallowed in robots.txt, Google might still index that URL, showing it in search results without a description (as it couldn't crawl the content). For guaranteed non-indexation, a
noindexmeta tag or X-Robots-Tag HTTP header is necessary. This is a critical distinction that many new SEOs miss. - Protecting Sensitive Areas: Beyond crawl budget, robots.txt can help keep sensitive areas like admin panels, staging environments, or user-specific dashboards out of the public eye in search results, even if it doesn't offer true security. It's a first line of defense against accidental exposure.
- Managing Dynamic Parameters: E-commerce sites often generate URLs with various parameters for sorting, filtering, and session IDs. Many of these parameters create duplicate content or low-value pages. Robots.txt can be used to disallow crawling of specific query parameters (e.g.,
Disallow: /*?sort=*), preventing Googlebot from getting lost in parameter variations.
Guide to Creating an SEO-Friendly Sitemap.xml
Basic Structure of a Sitemap.xml File
An SEO-friendly sitemap.xml adheres to the Sitemaps protocol agreed upon by major search engines like Google and Bing. The minimal structure includes an opening <urlset> tag declaring the namespace, inside which is a list of <url> tags. Each <url> tag contains an absolute path (loc), last modification date (lastmod), change frequency (changefreq), and priority. Loc is mandatory, while the other tags are optional but recommended to provide additional signals to bots.
Some tips when building your sitemap content:
- Include only canonical URLs that can be indexed; avoid pages blocked by noindex tags or robots.txt to prevent conflicting signals.
- Do not include pages returning 4xx or 5xx errors or redirect pages in the sitemap.
- Limit each file to a maximum of 50,000 URLs or 50MB; if exceeded, split into multiple files and use a sitemap index to compile them.
Understanding Sitemap Tags and Their Impact
While <loc> is the only mandatory tag, the optional tags provide valuable context:
<loc>(Location): The absolute URL of the page. This must be the full URL, including the protocol (e.g.,https://www.example.com/page.html). Ensure consistency with your preferred domain (www vs. non-www, http vs. https).<lastmod>(Last Modified Date): Indicates when the page was last modified. This helps search engines determine how frequently to re-crawl the page. Use the W3C Datetime format (YYYY-MM-DDThh:mm:ssTZD). For example,2023-10-27T10:00:00+00:00. Accuratelastmoddates can significantly speed up the re-indexing of updated content.<changefreq>(Change Frequency): Suggests how frequently the page is likely to change. Values includealways,hourly,daily,weekly,monthly,yearly, andnever. While search engines don't strictly adhere to this, it provides a hint. For a blog post,weeklyormonthlymight be appropriate, while a news article might bedaily.<priority>(Priority): Indicates the priority of a URL relative to other URLs on your site, with a value between 0.0 and 1.0. The default priority is 0.5. Higher priority pages are suggested to be crawled more frequently. For example, your homepage might have a priority of 1.0, while an old archive page might have 0.3. This is a suggestion, not a command, and Google often uses its own algorithms to determine crawl priority.
Sitemap Index Files for Large Sites
When your website grows beyond 50,000 URLs or 50MB for a single sitemap file, you must create a sitemap index file. This XML file simply lists other sitemap files. Its structure is similar to a regular sitemap, but instead of <urlset> and <url>, it uses <sitemapindex> and <sitemap> tags, with each <sitemap> containing a <loc> to another sitemap file.
<?xml version="1.0" encoding="UTF-8"?>
<sitemapindex xmlns="http://www.sitemaps.org/schemas/sitemap/0.9">
   <sitemap>
      <loc>https://www.example.com/sitemap1.xml</loc>
      <lastmod>2023-10-27T10:00:00+00:00</lastmod>
   </sitemap>
   <sitemap>
      <loc>https://www.example.com/sitemap2.xml</loc>
      <lastmod>2023-10-27T10:00:00+00:00</lastmod>
   </sitemap>
</sitemapindex>
How to Automatically Create Sitemaps for Popular Platforms
On WordPress, SEO plugins like Yoast SEO, Rank Math, or All in One SEO generate and continuously update sitemap.xml automatically with every new post, eliminating the need for manual actions. For custom-coded websites (PHP, Laravel, Node.js...), you'll need to write a script to extract data from the database and output it in the correct XML format. Set up a cron job to keep the sitemap in sync with the actual content. E-commerce platforms often generate sitemaps automatically, so administrators just need to verify and declare them to search engines.
After creation, always check by accessing the URL domain.com/sitemap.xml in a browser to ensure the file displays correctly in XML format, with no syntax errors or blank pages.
Practical Steps for Custom-Coded Websites
- Database Query: Write a script (e.g., in Python, PHP, Node.js) that queries your database for all relevant URLs. This typically involves selecting from your `posts`, `products`, or `pages` tables.
- Filter and Sanitize: Ensure you only select canonical, indexable URLs. Exclude drafts, private pages, or pages with `noindex` directives.
- Format as XML: Construct the XML structure according to the Sitemaps protocol, including
loc,lastmod,changefreq, andpriorityfor each URL. - Save to File: Save the generated XML content to `sitemap.xml` (or `sitemap_index.xml` if using an index) in your website's root directory.
- Automate with Cron Job: Schedule this script to run regularly (e.g., daily, weekly) using a cron job (on Linux servers) or a scheduled task (on Windows servers) to ensure the sitemap is always up-to-date.
- Handle Large Datasets: If your site has many URLs, implement pagination in your script to generate multiple sitemap files and then create a sitemap index file to list them all.
Guide to Creating a Proper Robots.txt File
Basic Syntax
The robots.txt file uses simple syntax, consisting of directive groups for each bot type (User-agent), followed by Disallow (to block crawl) or Allow (to permit crawl) lines applied to specific paths. A safe configuration for most websites allows all User-agents to access the entire site, only blocking specific admin or system folders, while declaring the sitemap.xml path at the end of the file to help search engines find it easily on their first visit.
Key Directives and Their Usage
User-agent:Specifies which web crawler the rules apply to.User-agent: *applies to all crawlers.User-agent: Googlebotapplies specifically to Google's main crawler.User-agent: Bingbotapplies to Bing's crawler.- You can have multiple
User-agentblocks for different bots. The most specific rule for a bot will be followed.
Disallow:Specifies paths or files that the User-agent should not crawl.Disallow: /admin/blocks all content within the/admin/directory.Disallow: /private-page.htmlblocks a specific file.Disallow: /wp-content/plugins/blocks all plugin files in WordPress.Disallow: /search?*blocks all URLs starting with/search?(useful for internal search results).
Allow:Used to allow crawling of a specific file or subdirectory within a disallowed directory. This is useful for selectively opening up access.Disallow: /wp-content/Allow: /wp-content/uploads/public-images/(allows images in this specific folder within the otherwise blockedwp-content).
Sitemap:Declares the location of your sitemap file(s). This is not a crawl directive but helps search engines quickly find your sitemap.Sitemap: https://www.example.com/sitemap.xml- You can list multiple sitemaps if you have them.
Example Robots.txt for a Typical WordPress Site
User-agent: *
Disallow: /wp-admin/
Allow: /wp-admin/admin-ajax.php
Disallow: /wp-includes/
Disallow: /wp-login.php
Disallow: /wp-content/plugins/
Disallow: /wp-content/themes/*/functions.php
Disallow: /trackback/
Disallow: /feed/
Disallow: /comments/feed/
Disallow: /category/*/feed/
Disallow: /*/attachment/
Disallow: /*/embed/
Disallow: /*/amp/
Disallow: /*?s=*
Disallow: /*?attachment_id=*
Disallow: /*?replytocom=*
Disallow: /xmlrpc.php
Disallow: /readme.html
Disallow: /license.txt

# Googlebot-specific directives (if any, otherwise * applies)
User-agent: Googlebot
Disallow: /old-staging-area/

Sitemap: https://www.example.com/sitemap_index.xml
Common Errors When Configuring Robots.txt
This file is easy to misconfigure, and the consequences can be severe, even causing the entire website to disappear from search results. Some errors to avoid include:
- Accidentally blocking the entire site with Disallow: / — a common mistake when transitioning a site from staging to production without removing the block directive.
- Incorrectly blocking directories containing CSS or JavaScript, preventing Googlebot from rendering the site correctly, affecting user experience evaluations.
- Confusing crawl blocking (robots.txt) with index blocking (meta noindex tag) — a page blocked from crawling can still appear in search results if linked to, although Google won't read its content.
- Incorrect file placement — robots.txt must be in the domain's root directory; placing it in a subdirectory renders it ineffective.
- Using robots.txt to hide sensitive information: As mentioned, robots.txt is a guideline, not a security measure. Malicious bots or users can easily view your robots.txt file and attempt to access disallowed URLs directly. Never put truly sensitive data behind a robots.txt disallow.
- Wildcard misuse: While
*is useful, incorrect placement can have unintended consequences. For example,Disallow: /folder*would block/folder/,/folder-name/, and/folder-something-else/. Be precise with your paths.
Testing Your Robots.txt File
Before deploying any changes to your live robots.txt, always test them. Google Search Console provides a Robots.txt Tester tool that allows you to paste your robots.txt content and test specific URLs to see if they would be blocked or allowed. This is an invaluable tool for preventing costly mistakes.
Registering with Google Search Console and Comparing the Two Files
Creating these files is just the beginning; you need to register them with search engines for effective crawling and indexing. In Google Search Console, go to Sitemaps, paste the sitemap.xml URL, and submit; Google will report the number of URLs discovered and successfully indexed. With robots.txt, the robots.txt Tester tool helps preview whether a specific path is blocked from crawling before applying changes to the live environment.
Though often mentioned together, the two files serve opposite purposes: sitemap.xml proactively "invites" — declaring the pages you want crawled and indexed; robots.txt "discourages" — specifying areas you do not want bots to visit. A well-optimized website needs both: sitemaps should only contain quality pages worth indexing, and robots.txt should eliminate duplicate or technical pages that do not add search value.
Google Search Console: Your Best Friend for Monitoring
Google Search Console (GSC) is a free web service by Google that helps website owners monitor their site's performance in Google Search. It's indispensable for managing sitemaps and robots.txt:
- Sitemaps Report: After submitting your sitemap, GSC will show you:
- When the sitemap was last read by Google.
- How many URLs Google discovered from your sitemap.
- How many of those URLs were actually indexed.
- Any errors encountered while processing the sitemap (e.g., malformed URLs, inaccessible pages).
- Robots.txt Tester: As mentioned, this tool allows you to test your robots.txt directives against specific URLs. It's crucial for debugging and ensuring your rules are working as intended. You can select different User-agents to see how different bots interpret your file.
- Coverage Report: This report in GSC shows you which pages are indexed, which have errors, which are excluded, and why. Understanding the "Excluded" section is vital, as it often points to pages blocked by robots.txt or
noindextags, or pages that Google deemed too low quality to index. By cross-referencing this with your sitemap and robots.txt, you can ensure your indexing strategy is aligned.
The Symbiotic Relationship: When to Use Which
It's crucial to understand when to use robots.txt and when to use other methods like noindex:
- Use Sitemap for:
- All important, canonical pages you want Google to index.
- New pages you want Google to discover quickly.
- Pages that might be deep within your site's architecture or have few internal links.
- Providing metadata like
lastmod,changefreq, andpriority. - Indicating alternate language versions (hreflang).
- Use Robots.txt for:
- Blocking crawling of low-value, duplicate, or private sections of your site (e.g., admin areas, internal search result pages, shopping carts).
- Managing crawl budget by preventing bots from wasting time on unimportant pages.
- Pointing to the location of your sitemap(s).
- Use
noindex(meta tag or X-Robots-Tag) for:- Pages you want to prevent from appearing in search results, even if they are linked to by other sites.
- Pages that Google might still discover and index despite being disallowed in robots.txt.
- This is the strongest directive for preventing indexation.
For example, a login page might be Disallowed in robots.txt (to save crawl budget) AND include a noindex tag (to ensure it never appears in search results, even if linked externally). A sitemap, on the other hand, would never include a login page.
This is just one of many technical factors that make up a comprehensive SEO strategy. Besides sitemaps and robots.txt, elements like title tags, meta descriptions, heading structure, page load speed, and internal linking also need to be handled in sync. If you lack the time or technical staff to fully implement these strategies, our On-page SEO Service at VSM can help review and optimize all these elements to Google standards. For a broader view of the tasks an SEO professional needs to handle, you can also check out the article SEO Traffic Techniques: How to Attract Users and Boost Website Traffic before starting your optimization journey.
Frequently Asked Questions
Is a sitemap.xml mandatory for small websites with only a few dozen pages? It's not absolutely mandatory since Googlebot can still crawl through internal links, but it is recommended due to the negligible cost and clear benefits in indexing speed, especially for new websites without many inbound links.
Can robots.txt block malicious bots and unauthorized data crawlers? No. Robots.txt is a voluntary guideline, adhered to by reputable bots like Googlebot and Bingbot, but malicious bots can completely ignore it. To truly block bad bots, additional measures like web application firewalls (WAF) or IP-based restrictions are necessary.
Should all URLs on a website be included in the sitemap.xml? No. Only include canonical URLs with valuable content that you want indexed. Internal search result pages, duplicate product filter pages, or unnecessary pagination should be excluded from the sitemap to maintain quality signals.
After updating robots.txt, does Google update it immediately or is there a waiting period? Google typically re-crawls robots.txt quite frequently (within 24 hours), but to ensure changes are applied immediately, you can use the robots.txt Tester tool in Search Console to prompt Google to read the latest file.
Can I use robots.txt to prevent pages from showing up in search results? No, not reliably. While disallowing a page in robots.txt prevents crawling, Google might still index the URL if it finds links to it from other places (e.g., external websites). To reliably prevent a page from appearing in search results, use a noindex meta tag or X-Robots-Tag HTTP header on the page itself.
What is the difference between a sitemap.xml and an HTML sitemap? A sitemap.xml is an XML file specifically for search engine crawlers, providing a structured list of URLs with metadata. An HTML sitemap is a human-readable page on your website, often linked from the footer, designed to help users navigate your site. While both aid discovery, they serve different primary audiences and purposes.